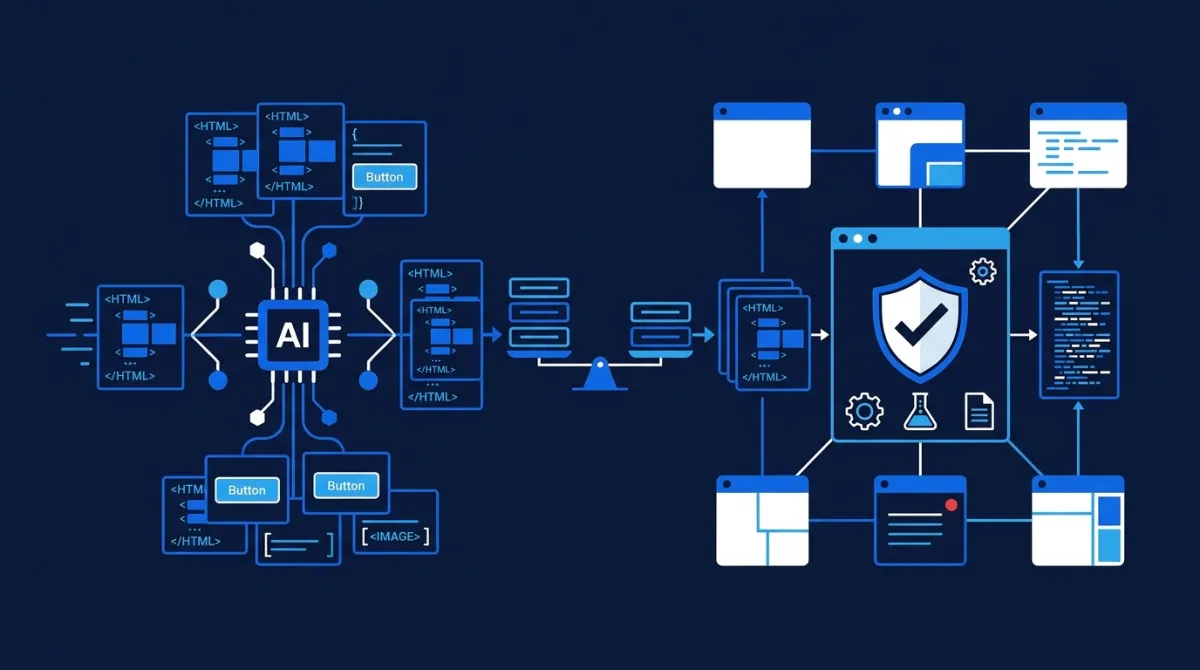
Do AI Coding Agents Improve Software Quality? Productivity, Technical Debt, and the Evidence
Introduction: More code does not automatically mean better software
AI coding agents can generate features, modify multiple files, run tests, investigate errors, and open pull requests with limited human intervention. Tasks that previously required hours of manual implementation can sometimes be completed in minutes.
That creates an attractive proposition for engineering teams: increase development throughput without increasing headcount.
But there is a distinction that is easy to overlook:
Generating code faster is not the same as delivering software faster.
A feature can be implemented quickly but still require extensive review, debugging, refactoring, security checks, and maintenance. If those downstream costs exceed the time saved during implementation, the apparent productivity improvement becomes misleading.
The important question is therefore not simply whether AI coding agents can write working code. It is whether they help teams deliver software that remains correct, secure, understandable, and maintainable over time.
Research published between 2025 and 2026 offers a more nuanced picture. Some studies report substantial task-level productivity improvements. Others identify slowdowns in mature repositories, additional maintenance concerns, or persistent issues in AI-generated contributions.
This article examines the evidence and translates it into practical engineering decisions.
1. First, distinguish productivity from code quality
Before comparing studies, it helps to separate the outcomes being measured.
| Dimension | What it measures | Example |
|---|---|---|
| Implementation speed | Time required to complete a task | A feature takes 30 minutes instead of 90 |
| Task completion | Whether the requested functionality works | The feature passes its acceptance tests |
| Code quality | Correctness, readability, security, and design | No obvious bugs or unsafe patterns |
| Maintainability | How easily developers can understand and modify the code | Another engineer can extend the feature |
| Delivery performance | How efficiently changes reach production | Pull requests are reviewed and deployed reliably |
| Long-term cost | Rework and maintenance after delivery | Bugs, refactoring, incidents, and technical debt |
These dimensions are related, but they are not interchangeable.
For example, an agent might generate 500 lines of code in a few minutes. That is a measurable increase in code production. However, if a developer spends another hour understanding and correcting those lines, the overall task may not have become faster.
A useful way to think about engineering productivity is:
Net productivity = value delivered − total engineering cost
Total engineering cost includes more than implementation:
- Prompting and task specification.
- Reviewing generated changes.
- Running and interpreting tests.
- Debugging incorrect assumptions.
- Refactoring unnecessary complexity.
- Security and dependency checks.
- Future maintenance.
The value delivered must be assessed against this entire lifecycle.
2. What does the research actually show?
There is no single universal result. The findings depend on the task, developer experience, repository complexity, tool capabilities, and evaluation method.
2.1 AI can significantly accelerate some development tasks
A 2026 study published in Empirical Software Engineering, titled Echoes of AI: Investigating the downstream effects of AI assistants on software maintainability, provides useful evidence.
The researchers conducted a two-phase controlled experiment involving 151 participants, 95% of whom were professional developers.
In the first phase, developers implemented a feature in a Java web application, with or without AI assistance.
The results showed:
- A 30.7% median reduction in task completion time when using an AI assistant.
- An estimated 55.9% speedup among habitual AI users.
This supports the idea that AI assistance can improve implementation speed, particularly when developers know how to use the tools effectively.
However, the second phase examined something different: whether another developer could maintain and extend the resulting code without AI assistance.
The researchers found no statistically significant differences in subsequent completion time or code quality between AI-assisted and manually developed solutions.
That is an important distinction. Faster implementation did not automatically produce more maintainable software, but the study also did not find systematic maintainability degradation.
2.2 AI can slow down experienced developers in complex repositories
A particularly interesting counterexample comes from METR's randomized controlled trial, published in July 2025.
The study involved:
- 16 experienced open-source developers.
- 246 real issues from mature repositories.
- Projects averaging more than one million lines of code.
- Developers with an average of several years of experience in their repositories.
Developers were randomly assigned tasks with or without access to AI tools.
The result was surprising: developers took 19% longer when AI tools were allowed.
They had expected AI to reduce completion time by 24%. Even after experiencing the slowdown, participants still believed AI had made them faster.
Why did this happen?
The environment matters. Experienced developers working in mature repositories already understand the architecture, conventions, and history of their projects.
AI assistance can introduce additional work:
- Explaining repository-specific context.
- Checking whether suggestions follow existing conventions.
- Correcting incorrect assumptions.
- Reviewing generated changes.
- Integrating code that does not fit the existing architecture.
The result should not be generalized to every developer or every coding task. METR explicitly describes its findings as a snapshot of early-2025 tools in a specific setting.
Nevertheless, it demonstrates why benchmark performance and real-world productivity are different measurements.
2.3 More code production can mean more editing and verification
A longitudinal study from JetBrains Research, published in January 2026, examined two years of IDE telemetry from 800 developers, alongside a survey of 62 professionals.
The researchers found that AI users produced substantially more code, but also deleted significantly more code.
This suggests that AI-assisted development changes the nature of the workflow. Developers are not simply typing less. They are generating, inspecting, editing, accepting, and rejecting larger volumes of proposed code.
The study also highlights a measurement problem: developers may perceive productivity improvements even when the underlying workflow includes considerably more editing activity.
The practical implication is that code volume and accepted suggestions are weak proxies for engineering productivity.
A better measurement asks how much validated functionality reaches the codebase, and what effort is required to get it there.
3. The technical debt question: What happens after the code is merged?
Technical debt is not limited to badly written code.
It includes shortcuts and design decisions that make future changes more expensive. Examples include duplicated logic, unclear abstractions, unnecessary dependencies, weak error handling, and insufficient tests.
AI-generated code can introduce these problems for several reasons.
3.1 Code duplication
An agent may implement a new function without recognizing that similar functionality already exists elsewhere.
Instead of reusing an established service, it creates another implementation.
This may solve the immediate task, but it increases the number of places that must be updated when the business logic changes.
3.2 Unnecessary abstraction
AI-generated solutions sometimes introduce additional classes, interfaces, configuration layers, or helper functions that do not provide meaningful value.
A simple operation can become a complicated structure.
The issue is not abstraction itself. Good abstraction reduces complexity. Unnecessary abstraction merely moves it elsewhere.
3.3 Inconsistent architecture
A coding agent may produce a technically valid implementation that does not follow the project's existing architecture.
For example, a Laravel application might already use service classes and dependency injection for business logic. An agent could bypass those conventions and put database operations directly into a controller.
The code may work, but the result becomes harder to maintain consistently.
3.4 Weak error handling and testing
An agent may focus on the successful execution path while overlooking:
- Invalid input.
- Missing records.
- Database failures.
- Permission boundaries.
- Concurrent operations.
- Unexpected API responses.
Passing a basic test does not prove that all important behaviors have been validated.
4. Evidence from real repositories: AI-introduced issues can persist
One of the most relevant 2026 studies is Debt Behind the AI Boom: A Large-Scale Empirical Study of AI-Generated Code in the Wild.
The researchers analyzed 304,362 verified AI-authored commits across 6,275 GitHub repositories. Their dataset covered five coding assistants.
They identified 484,606 distinct issues introduced in the analyzed commits.
The study reported three important findings:
- Code smells represented 89.1% of the identified issues.
- More than 15% of commits from each studied assistant introduced at least one issue, although rates varied by tool.
- 24.2% of tracked AI-introduced issues remained in the latest repository revision.
The last finding deserves attention.
An issue introduced by an AI assistant does not necessarily disappear after the pull request is merged. Some issues remain in the repository and become part of its maintenance burden.
However, the findings require careful interpretation.
The dataset identifies AI-authored commits through visible Git metadata. It does not represent every AI-assisted contribution, and static-analysis findings are not equivalent to confirmed production defects.
A code smell is not necessarily a bug. Likewise, the presence of a static-analysis warning does not prove that a system is unreliable.
The study does not establish that AI-generated code is inherently worse than human-written code in every situation.
It does provide evidence that AI-introduced issues can survive in real repositories and that stronger quality assurance is necessary.
5. The organizational effect: Faster code generation can create slower delivery
The problem becomes more complex when AI adoption happens across an entire engineering team.
Imagine a team of six developers.
Before adopting coding agents, each developer produces a manageable number of changes. Pull requests are relatively small, reviewers understand the context, and the team can maintain a predictable release process.
After adopting coding agents, developers can generate substantially larger changes.
But the review process has not changed.
Now reviewers must inspect more code, identify more potential edge cases, verify generated tests, and understand changes that may span multiple modules.
The bottleneck moves from implementation to verification.
This is consistent with the broader findings of Google's 2025 DORA research.
DORA describes AI as an amplifier of an organization's existing strengths and weaknesses. The benefits of AI adoption depend heavily on the engineering system surrounding the tools.
A team with strong automated testing, clear architecture, fast feedback loops, and effective code review is better positioned to benefit.
A team with weak testing, unclear ownership, and slow review processes may simply generate problems faster.
This is why introducing coding agents should not be treated as an isolated tooling decision. It is an engineering process change.
6. How should engineering teams measure AI coding agents?
A team should avoid evaluating coding agents using only lines of code, number of generated files, accepted suggestions, or raw task completion time.
These metrics can be useful for understanding activity, but they do not establish whether the team is delivering better software.
A more useful evaluation framework has four layers.
Layer 1: Implementation efficiency
Measure whether developers complete comparable tasks more efficiently.
Useful metrics:
- Time from task start to a review-ready pull request.
- Time spent prompting and correcting the agent.
- Number of iterations before acceptance.
- Percentage of tasks completed successfully.
- Developer time spent on implementation versus verification.
Layer 2: Change quality
Measure the quality of the actual changes.
Useful metrics:
- Automated test pass rate.
- Regression rate.
- Static-analysis findings introduced by changes.
- Security vulnerabilities.
- Code duplication.
- Review rejection and rework rates.
Layer 3: Delivery performance
Measure what happens after code review.
Useful metrics:
- Pull-request lead time.
- Deployment frequency.
- Change failure rate.
- Time required to restore service after a failure.
- Time waiting for review and approval.
These measurements are closely related to established software delivery performance frameworks, including DORA.
Layer 4: Long-term maintainability
This is where many short-term AI evaluations fall short.
Track:
- Repeated fixes to recently generated code.
- Code complexity trends.
- Growth in duplicated logic.
- Time required to modify existing features.
- Maintenance work generated by earlier changes.
- Whether developers can explain and safely modify the code.
A team should compare these indicators before and after AI adoption, using comparable projects and task types where possible.
The objective is not to prove that AI is beneficial. It is to identify where it actually improves engineering outcomes.
7. A practical quality-control workflow for coding agents
Coding agents should operate within an engineering process that makes their output verifiable.
A reliable workflow can be organized into six stages.
Step 1: Define the task before generating code
Give the agent a clear objective, relevant context, and explicit constraints.
A useful task description should include:
- The expected behavior.
- Relevant files and components.
- Existing architectural conventions.
- Acceptance criteria.
- Out-of-scope changes.
For example, instead of asking:
Add farmer management to the application.
Specify:
Implement farmer creation using the existing Laravel conventions. Validate required fields, preserve existing relationships, use the established service layer, and add tests for successful creation and invalid input. Do not modify unrelated modules.
Clear specifications reduce ambiguity and make generated changes easier to review.
Step 2: Keep changes small and scoped
Avoid asking an agent to redesign an entire application when the task only requires one feature.
Prefer incremental changes:
- Inspect the existing implementation.
- Propose the approach.
- Implement one component.
- Run relevant tests.
- Review the result.
- Continue to the next component.
Smaller changes make errors easier to isolate and reduce the cost of review.
Step 3: Require tests, but do not trust generated tests blindly
Agents can generate useful unit and integration tests.
However, generated tests may reproduce the same incorrect assumptions as the implementation.
A test that only confirms the agent's interpretation of a requirement is not sufficient.
Reviewers should verify that tests cover:
- Expected behavior.
- Boundary conditions.
- Invalid input.
- Failure scenarios.
- Authorization.
- Regression risks.
For critical functionality, independently derived acceptance tests are especially important.
Step 4: Run automated quality checks
A coding agent's completion message is not proof that the implementation is correct.
Use automated checks such as:
- Unit and integration tests.
- Static analysis.
- Linters and formatters.
- Dependency vulnerability scanning.
- Secret detection.
- Type checking where applicable.
- Build and deployment validation.
The agent can help interpret failures, but the checks should run independently of the agent's own claims.
Step 5: Review architectural consistency
A reviewer should ask:
- Does this follow the project's established conventions?
- Is existing functionality being duplicated?
- Are new dependencies necessary?
- Is the error handling appropriate?
- Does the implementation introduce unnecessary complexity?
- Can another developer understand and modify this code?
A technically correct implementation can still be a poor architectural decision.
Step 6: Monitor the code after deployment
Quality assurance does not stop when a pull request is merged.
Monitor production errors, performance regressions, security alerts, and repeated fixes.
If an AI-generated change causes recurring problems, use those findings to improve the team's task specifications, coding guidelines, tests, and agent permissions.
The goal is to build a feedback loop between code generation and actual software behavior.
8. Where do AI coding agents provide the most value?
Not every engineering task has the same risk or complexity.
The following matrix offers a practical starting point.
| Task type | Potential value | Recommended approach |
|---|---|---|
| Boilerplate and repetitive code | High | Delegate with tests and review |
| Documentation and code explanation | High | Use AI, verify technical accuracy |
| Unit-test scaffolding | High | Review coverage and assertions |
| Small, isolated bug fixes | High | Require reproduction and regression tests |
| Refactoring across multiple modules | Medium | Use small steps and careful review |
| Complex architectural changes | Variable | Human-led design, AI-assisted implementation |
| Authentication and authorization | High risk | Strict review and security testing |
| Financial or safety-critical logic | High risk | Human ownership and independent verification |
| Large autonomous codebase modifications | Variable | Restrict scope and require staged approval |
The distinction is not that AI should never touch complex systems.
It is that the cost of an incorrect change increases with the consequences and complexity of the task.
Teams should allocate verification effort according to risk, not simply according to how confident the agent sounds.
9. The human role is shifting from writing code to supervising changes
AI coding agents are changing the distribution of engineering work.
Developers increasingly spend time:
- Defining requirements.
- Providing context.
- Selecting implementation strategies.
- Reviewing generated changes.
- Investigating failures.
- Validating behavior.
- Making architectural decisions.
This does not eliminate the need for engineering knowledge.
In fact, the ability to evaluate code becomes more important when code can be generated at a much higher rate.
A developer who cannot recognize an incorrect database query, insecure authorization check, or unnecessary abstraction may accept a flawed implementation simply because it looks complete.
The risk is not only technical debt. It is also a gradual loss of understanding of the systems being maintained.
The 2026 IEEE study More Code, Less Understanding? On the Impact of AI Assistants on Developers’ Productivity and Code Ownership adds another dimension. In an experiment involving 69 participants, AI-assisted developers achieved greater task completeness, but showed a 12.5% reduction in their ability to answer technical questions about the code they had implemented.
This does not prove that every AI-assisted workflow weakens developer understanding. It does reinforce the importance of code ownership: developers should understand the changes they approve and maintain.
AI should reduce mechanical effort without removing human responsibility.
10. A decision framework: How should teams adopt coding agents?
Instead of asking whether the team should use AI everywhere, evaluate adoption through a controlled process.
Start with a baseline.
Measure task completion time, review duration, defects, rework, and delivery performance before introducing the tool.
Choose representative tasks.
Include repetitive tasks, isolated bug fixes, feature development, and more complex changes. Do not evaluate an agent using only easy demonstrations.
Run a controlled pilot.
Compare similar tasks with and without AI assistance. Record both implementation time and downstream review and correction effort.
Track quality over time.
A short pilot can reveal immediate productivity effects, but maintainability and technical debt require longer observation.
Expand only where the evidence supports it.
If AI reduces implementation time without increasing rework or quality problems, expand its use in that workflow.
If it generates more code but increases review time, narrow the scope or improve the verification process.
The result should be a task-specific adoption strategy rather than a company-wide target for AI-generated code.
Conclusion: The real productivity metric is reliable software delivered
AI coding agents have demonstrated the ability to accelerate many software development tasks. Research also shows that the benefits are not universal and that code generation can introduce issues that require additional review and maintenance.
The evidence does not support either extreme: that AI automatically improves software quality, or that AI-generated code is inherently unmaintainable.
The more defensible conclusion is that AI changes where engineering effort is spent.
Implementation can become faster, while specification, review, testing, integration, and maintenance become more important.
For engineering teams, the objective should not be to maximize generated code or minimize human involvement.
It should be to increase the amount of reliable, maintainable software delivered per unit of engineering effort.
The best coding agent is not necessarily the one that writes the most code or completes the most benchmark tasks. It is the one that helps a team deliver changes that remain correct and understandable after the agent has finished.
Sources and further reading
-
Borg et al. (2026) — Echoes of AI: Investigating the downstream effects of AI assistants on software maintainability, Empirical Software Engineering.
https://doi.org/10.1007/s10664-026-10889-1 -
Liu et al. (2026) — Debt Behind the AI Boom: A Large-Scale Empirical Study of AI-Generated Code in the Wild.
https://arxiv.org/abs/2603.28592 -
METR (2025) — Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity.
https://metr.org/blog/2025-07-10-early-2025-ai-experienced-os-dev-study/ -
JetBrains Research (2026) — Evolving with AI: A Longitudinal Analysis of Developer Logs.
https://kairos.jetbrains.com/research/publications/evolving-with-ai -
DORA (2025) — The State of AI-assisted Software Development.
https://dora.dev/research/2025/dora-report/ -
IEEE Transactions on Software Engineering (2026) — More Code, Less Understanding? On the Impact of AI Assistants on Developers’ Productivity and Code Ownership.
https://doi.org/10.1109/TSE.2026.3679627 -
Google Cloud / DORA — Research and measurement frameworks for software delivery performance.
https://dora.dev/