Why AI Agents Are Breaking Traditional Load Balancing
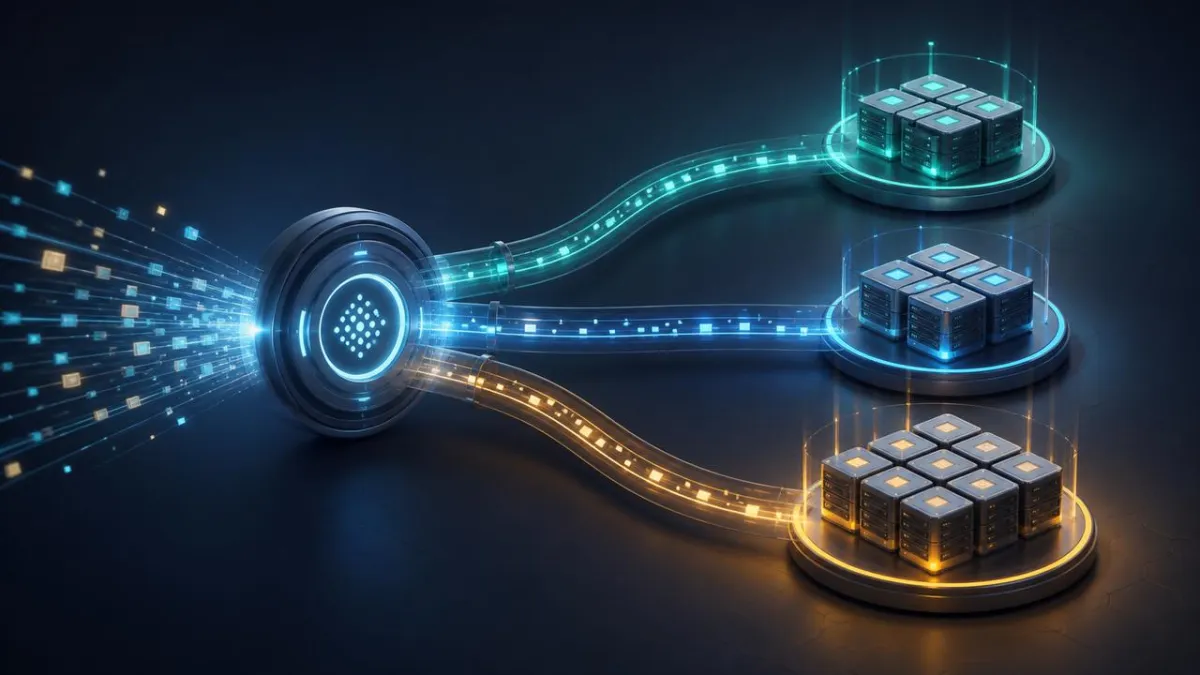
As AI shifts from single prompts to long-running, multi-step tasks, inference infrastructure needs to optimize more than traffic distribution. Context, memory, latency, and workload priority are becoming routing decisions.
The load balancer was built for a different workload
Traditional load balancing solves a straightforward problem: distribute incoming requests across available servers so that no single machine becomes a bottleneck.
A common strategy is round-robin routing. The first request goes to one server, the next to another, and the process continues. Other approaches consider server health, active connections, or current load.
For many web applications, this is sufficient. Requests are often independent, and one server can usually handle a request without needing the computational state of a previous request.
AI inference introduces a different set of constraints.
A request to a large language model (LLM) is not just a small payload that needs to reach an available server. Processing it may involve thousands of tokens, expensive accelerator computation, and a growing internal representation of the conversation known as the key-value (KV) cache.
When an AI application becomes an agent that repeatedly calls a model, invokes tools, observes results, and continues reasoning, those costs accumulate across a sequence of related requests.
The infrastructure is no longer serving only isolated prompts. It is serving evolving computational sessions.
That distinction changes how requests should be routed.
Why agent workloads change the equation
Consider a coding agent asked to fix a bug in a large repository.
Its workflow might look like this:
- Read the task and inspect the relevant files.
- Ask the model to identify a likely cause.
- Call a search or terminal tool.
- Send the tool output back to the model.
- Generate a patch and run tests.
- Inspect the results and revise the patch.
Each model invocation may depend on context accumulated during previous steps. Some implementations resend substantial portions of the conversation or repository context; others preserve and reuse state through their serving infrastructure.
Either way, the workload has characteristics that a simple request counter cannot fully capture.
First, requests are related. Several calls may share the same system instructions, conversation history, repository files, or other long prefixes.
Second, demand is bursty. An agent can generate a sequence of model calls, launch multiple sub-agents, or trigger parallel tool workflows. A seemingly small user request can create a large amount of backend traffic.
Third, requests have different latency requirements. A user waiting for an answer has a different experience from a background agent running a long evaluation. Treating both workloads identically can allow background traffic to degrade interactive performance.
Fourth, the model's internal state is expensive to manage. Recomputing context and moving cached state between accelerators can consume time and memory that could otherwise serve new requests.
These characteristics make agent workloads less predictable than a stream of independent chat prompts.
The hidden cost: losing context locality
One of the most important concepts in modern LLM serving is KV-cache reuse.
During inference, a transformer model builds key and value tensors as it processes tokens. These tensors allow the model to reuse previous computation when generating subsequent tokens, rather than recomputing everything from scratch.
For long prompts and multi-turn interactions, the KV cache can represent a substantial amount of work already completed.
Now imagine that an agent sends a follow-up request to a cluster with four model replicas.
The first request is processed by Replica A. The next request, containing much of the same context, is routed to Replica C because the load balancer sees it as the next available destination.
Replica C may not have the relevant cached context. Depending on the serving implementation and cache configuration, it may need to recompute the shared prefix or retrieve cached state from another storage tier.
The cluster has distributed the requests, but it has potentially discarded some of the benefit of previous computation.
This is the difference between balancing traffic and balancing useful work.
A server with a slightly higher request count might still be the best destination if it already holds the context needed for the incoming request. Conversely, sending every request to the same replica is not optimal if that replica is overloaded.
The routing problem therefore becomes a trade-off among cache locality, current load, predicted latency, and available capacity.
From round-robin to cache-aware routing
This is the problem that newer inference-serving architectures are designed to address.
On October 20, 2026, Google Cloud announced llm-d 1.0, an open-source, Kubernetes-native stack for distributed LLM inference. Its capabilities include cache-aware routing, session-aware routing, tiered KV-cache management, and traffic flow control. The project brings inference engines and cloud-native orchestration together rather than treating model serving as a collection of independent endpoints.
The central idea is simple: the router should consider not only which replica can accept a request, but also which replica is likely to serve it efficiently.
A cache-aware router can consider whether a destination already holds a relevant prefix. A load-aware router can account for the destination's current workload. A latency-aware strategy can estimate which placement is likely to meet the request's performance target.
These signals can conflict.
- The replica with the best cache match may be heavily loaded.
- The least-loaded replica may have to recompute a long context.
- A latency-sensitive request may deserve priority over a background task.
- A burst of agent requests may need controlled queuing rather than unrestricted dispatch.
A production router must weigh these competing objectives rather than blindly optimize a single metric.
The important architectural shift is that the routing layer becomes aware of inference-specific state and workload characteristics.
Why this matters for infrastructure costs
Accelerators are expensive resources, and efficient utilization is not simply a matter of keeping every GPU busy.
A cluster can show high utilization while spending too much time recomputing shared context, moving cache data, or processing requests that compete with more urgent work. Conversely, an overly conservative scheduler can leave capacity idle.
The objective is to maximize useful inference work while meeting latency and reliability targets.
Cache-aware routing is one part of that equation. Other techniques address different bottlenecks:
Tiered KV-cache storage. Frequently used state can remain in accelerator memory, while less immediately accessible state may be offloaded to host memory or other storage tiers. This expands the amount of context that can be retained, though retrieving offloaded state has its own latency and bandwidth costs.
Prefill/decode disaggregation. Processing the input prompt and generating output tokens have different computational characteristics. Separating these stages into different resource pools can allow each to scale more independently, provided the transfer and coordination overheads are justified.
Priority-aware flow control. Interactive requests, background jobs, and bursty agent workflows can compete for the same serving fleet. Queues, quotas, and priority policies help prevent one class of traffic from consuming all available capacity.
Inference-aware autoscaling. Scaling decisions can consider signals such as queue depth, resource saturation, and predicted latency instead of relying exclusively on generic CPU or memory utilization.
These techniques are complementary. Better routing cannot compensate for insufficient capacity in every situation, and adding more GPUs will not automatically eliminate inefficient cache placement or poor scheduling.
The challenge is to coordinate them around the workload the system actually serves.
What the latest results tell us—and what they don't
Google Cloud reported that, on a particular agentic coding workload using Ironwood TPU hardware, prefix-aware routing combined with host-memory offloading reduced median time to first token by more than 85% and increased total throughput by 2.4 times compared with a plain Kubernetes Service.
Those results are a useful indication of how much routing and cache management can matter under the right conditions. They are not a universal performance guarantee.
The outcome depends on factors such as prompt length, prefix reuse, concurrency, model architecture, cache capacity, hardware, workload distribution, and the baseline being compared. A workload with mostly unrelated, short requests may benefit less than one with long, repeatedly reused contexts.
Teams should therefore evaluate these systems against representative traffic rather than selecting an architecture based on a headline benchmark.
Useful measurements include:
- Time to first token (TTFT): How long users wait before generation begins.
- Inter-token latency (ITL): How quickly subsequent tokens are generated.
- End-to-end task latency: How long an agent takes to finish the complete workflow, including tool calls and retries.
- Throughput: How much useful work the system completes over time.
- Cache hit rate and recomputation: How effectively the serving system reuses previously processed context.
- Cost per completed task: Whether the infrastructure improvement translates into lower real operating costs.
The final metric deserves particular attention. An agent that makes fewer redundant model calls and completes its task reliably may be more economical than one that produces more tokens per second but requires additional retries or verification.
The new routing layer must understand workload priorities
As agent systems mature, a single inference endpoint may serve several different kinds of work:
- A developer waiting for an interactive coding response.
- A background agent reviewing hundreds of files.
- A multi-agent workflow performing parallel research.
- An evaluation pipeline generating thousands of model responses.
- A long-running task that repeatedly reuses a large context.
These workloads compete for the same underlying resources, but they should not necessarily receive the same treatment.
An interactive request may need a tight latency target. A background evaluation may tolerate queuing if it improves overall throughput. A long-running agent may benefit from session affinity and cache reuse, while a newly arriving request may need to be routed elsewhere to avoid a congested replica.
This creates a scheduling problem that extends beyond ordinary load balancing.
The serving platform needs policies that account for request priority, context locality, resource availability, fairness between tenants, and service-level objectives. It must also avoid allowing one long-running session or one noisy tenant to monopolize the system.
The goal is not to make every request take the same path. It is to make each routing decision serve the overall objectives of the platform.
What engineering teams should do next
Not every AI application needs a specialized distributed inference stack. A low-volume application using a managed model API may never need to operate its own routing infrastructure.
The case becomes stronger when a team controls its own model-serving fleet and faces long contexts, repeated prompts, high concurrency, multiple tenants, or demanding latency targets.
For those teams, a practical evaluation can start with five steps.
1. Establish a representative baseline. Measure latency, throughput, resource utilization, and cost under realistic agent sessions—not only isolated prompt benchmarks.
2. Measure context reuse. Determine how much of the incoming traffic shares system prompts, conversation history, or other reusable prefixes. Cache-aware routing has limited value if the workload rarely reuses context.
3. Test routing strategies. Compare round-robin or existing load balancing against cache-aware and load-aware routing while keeping the model, hardware, and workload as consistent as possible.
4. Introduce workload priorities. Test whether background jobs can be queued or throttled without violating their completion requirements, and whether interactive latency remains stable during bursts.
5. Evaluate the complete task. Track agent completion time, failures, retries, and cost per successful task. An improvement in TTFT is useful, but it is only one part of the user experience.
The results should determine whether the added infrastructure complexity is justified. More sophisticated routing introduces its own operational costs: additional components, telemetry, tuning, failure modes, and scheduling decisions that must be maintained.
The bigger shift: inference is becoming a systems problem
For years, progress in AI was often discussed in terms of model capabilities: larger context windows, better reasoning, improved coding, or higher benchmark scores.
Those improvements still matter. But as AI applications become agents that repeatedly invoke models and tools, the performance of the overall system increasingly depends on how computation is scheduled and reused.
A model may be capable of solving a task, yet the deployed system can still be slow or expensive because it repeatedly processes the same context, routes requests without considering cached state, or allows background traffic to overwhelm interactive work.
That is why inference routing is becoming a more specialized discipline.
The next generation of serving infrastructure will not simply ask, Which server should receive this request? It will increasingly ask, Which destination can make the best use of the work already done, while meeting this request's latency, priority, and reliability requirements?
That is a more demanding problem than traditional load balancing—and one that agentic AI makes difficult to ignore.
Sources and further reading
- Google Cloud — Announcing llm-d 1.0: Open distributed inference for agents on Google Cloud TPUs and GPUs (October 20, 2026). Primary source for llm-d's architecture, routing capabilities, and reported benchmarks.
- IBM — llm-d 1.0 Advances Open, Cost-Efficient AI Inference for Production Scale (October 20, 2026). Additional project and production-serving context.
- llm-d — Project repository and technical documentation. Open-source implementation, architecture, and benchmark resources.