 AI Productivity
AI Workload Scheduling: Building Cost-Aware LLM Pipelines for Production
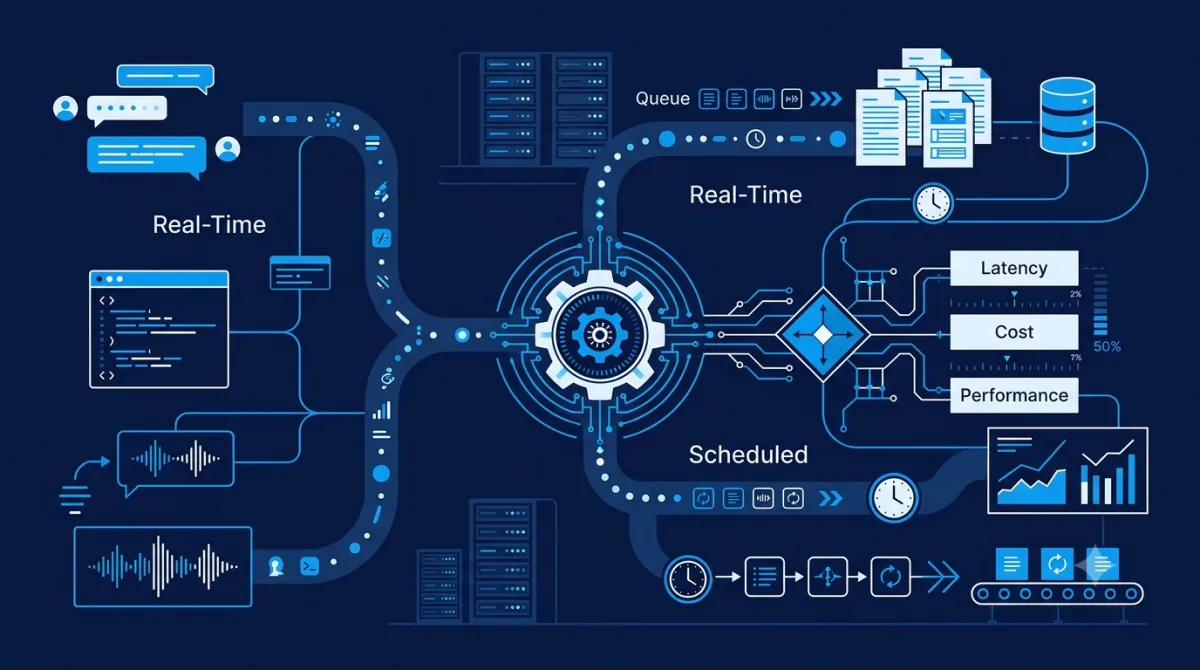
The next competitive advantage in AI won't come from choosing a better model—it will come from using the right model at the right time. As inference costs continue to rise, engineering teams are beginning to treat AI workloads like cloud infrastructure: something to orchestrate, schedule, and optimize rather than simply execute. This guide explores how to build cost-aware AI pipelines that automatically route and schedule LLM workloads based on urgency, latency requirements, and pricing. Using emerging trends like DeepSeek V4's peak-valley API pricing as a catalyst, we'll show why AI workload scheduling is becoming a core architectural capability rather than an optimization reserved for hyperscalers.